We build AI’s next challenge.
From real-world expert work to rigorous RL environments and evaluations, we turn human expertise into measurable AI progress.
Why copula
"In linguistics, a copula is the linking verb — is, are — that binds subject and predicate. In mathematics, a copula captures coupling: it joins separate marginal distributions into a true joint distribution, as in Sklar's theorem. Capability benchmarks and real-world deployment are two marginals. Most companies measure each in isolation. We model the dependence between them, especially the tails where models actually fail."
— COPULA LAB
Why trust us
Credibility — from the people to the method.
Founders
A team that closed the loop inside model companies across post-training, agent product deployment, customer delivery, and commercial growth.
Experts
A vetted network of specialists from top firms, labs, and professional institutions, bringing the judgment, workflows, and edge cases that only practitioners know.
Methodology + Data Infra
A technical pipeline for expert task decomposition, rubrics, gold deliverables, QC, and RL-environment generation.
The problem
Frontier models still fail on
expert work.
Text models have become broadly capable, but industry adoption is still capped by deep vertical work: complex financial analysis, multi-step legal reasoning, and cross-domain scientific tasks.
The bottleneck is not more generic answers. Enterprise deployment depends on tacit expert judgment and long-horizon workflows, yet most of that knowledge is never written down or converted into verifiable training environments.
Closing the gap requires people who can turn human experts’ tacit cognition into trainable, evaluable, and scalable environments for models.
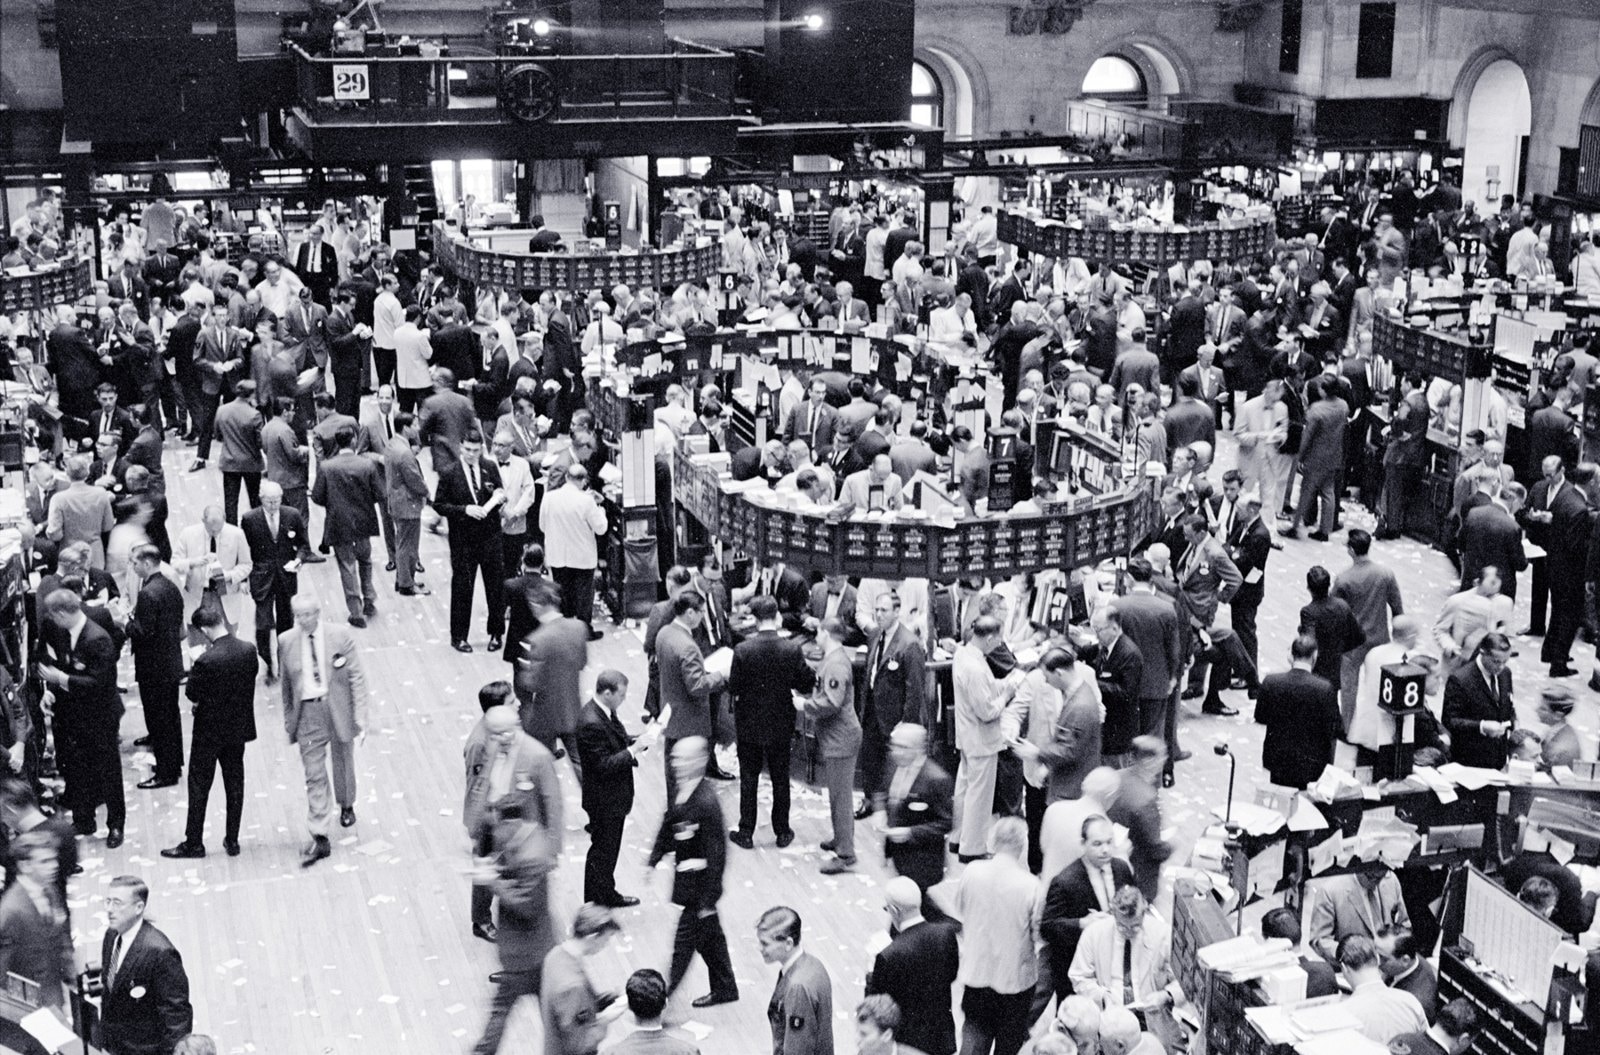
Photo: Thomas J. O’Halloran, U.S. News & World Report Collection, Library of Congress.
What we build
Four building blocks for capable models.
Data
Domain-specific training data produced by verified experts — not commodity annotators. Designed for the reasoning depth frontier models actually need.
Environments
Realistic task environments that capture professional workflows across tool use, multi-step dependencies, and long-horizon execution.
Expert Network
Specialists in finance, law, medicine, and STEM research — vetted, structured, and deployed at scale through a managed expert ecosystem.
Evaluation
Benchmarks that measure failure modes, not just average performance. We test the tails — where models break in ways that matter.
Benchmarks
The benchmarks we are building.
All benchmarks3D

Verifiable 3D scenes and assets
The 3D benchmark combines multi-file projects, spatial reasoning and runnable verification scripts to turn “was the 3D result generated correctly?” into automatically checkable criteria.
Finance Agent

Long-horizon finance in Chinese workflows
Chinese financial conventions, compliance workflows and multi-role collaboration. Experts define open-ended tasks, office-document deliverables and evaluation rubrics.
Who we serve
Built for the teams
shipping frontier models.
The teams building frontier models come to us for the data and environments that move capability where it actually matters.
Post-training
Expert-workflow SFT and RL-environment data that moves capability on real professional tasks — not commodity labels.
Agent training
Long-horizon, multi-turn task environments with expert trajectories, scoring functions, and gold deliverables.
Evaluation
High-impact benchmarks and bad-pattern datasets that surface where models actually fail — and open procurement.
Data procurement
Packaged, verifiable, repeatable data products designed to scale — not bespoke, case-by-case work.
Why us
How we're different.
Model-native perspective
Both founders built benchmark and evaluation systems at frontier labs. We understand the actual bottlenecks from the inside — not from the outside looking in.
Global ecosystem reach
Proven track record of international open-source launches and revenue growth across domestic and overseas markets. We reach the labs that matter.
Deployment taste
We stay close to agent deployment and model usage, so we can spot the verticals where application potential is about to compound and turn them into trainable, evaluable data products.
Bring models into real expert work.
We work directly with frontier model teams. Reach out to discuss data needs, benchmark access, or expert collaboration.
Talk to us